> ## Documentation Index
> Fetch the complete documentation index at: https://docs.mathfi.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# Feature Refinery
> Feature Refinery removes the columns that do not help your prediction, and tells you which ones did. Inputs, outputs, decision rule, limits and timings.
Feature Refinery answers one question: **which of my columns actually help?**
It works the way a careful analyst would, if they had the time. Remove one column, retrain, see
whether the prediction got better or worse. Put it back if it was needed. Move to the next column.
Repeat over every column. What takes a person weeks, and usually never gets done properly, runs
unattended here.
## What you put in
Two labelled CSVs:
| File | What it is |
| --------- | --------------------------------------------------------- |
| **Train** | Roughly 80% of your labelled rows, with the target column |
| **Test** | The other 20%, **with its labels kept** |
Both keep their labels. The test file is how each candidate column set gets marked; the run never
learns from it, it only scores against it. Same columns, same order, in both.
One setting: **number of buckets** (4, 10 or 20). Higher can refine more accurately and takes
longer. 10 is the recommended starting point. See [Tuning](/guides/hyperparameter-tuning).
Details of column layout and what makes a file acceptable are in
[Input data](/guides/input-csv-creation).
## What you get out
Your train file with the removed columns dropped.
The same treatment applied to your test file, so the pair still matches.
One `KEEP` or `REMOVE` per original column, in header order. Downloadable as CSV.
You also get the two things the run learned that the next stage needs:
* **The performance target the refined data reached.** Carry this into training. It is the single
most important number the run produces.
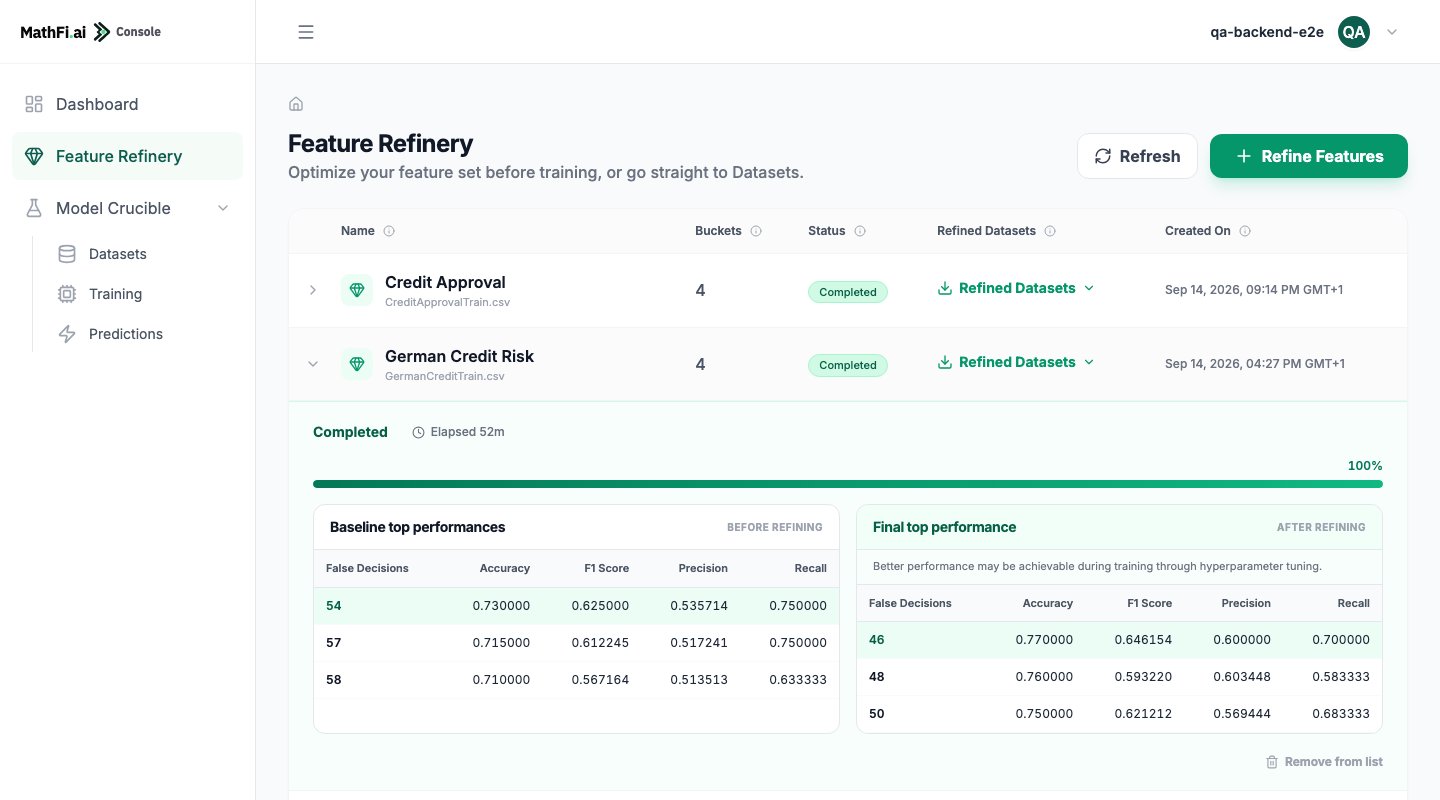
* **Baseline and final performance tables.** What the best models scored before refining and after,
so the improvement is visible rather than asserted.
 ## How it decides
The run first establishes a baseline: it trains many models on your data with every column present,
and records how many decisions the best of them got wrong.
Then, one column at a time, it removes the column, retrains the same way, and compares. A column is
removed for good only when performance holds up without it. Otherwise the column goes back and the
run moves on. Every removal re-bases the comparison, so each decision is made against the best the
data has managed so far, not against where it started.
Three things can happen to a column:
| Outcome | What it means |
| ------------------- | ------------------------------------------------------------------------------------- |
| **REMOVE** | Performance held without it. The column was noise, or worse than noise. |
| **KEEP** | Performance dropped without it. The column carries signal. |
| **KEEP (collapse)** | Training could not produce a model at all without it. Foundational to the prediction. |
The third case is the interesting one. Every dataset has a few columns the prediction is built on;
removing one does not degrade the model, it destroys it. Expect a handful, and do not treat them as
a problem.
Results vary run to run. The same inputs can give different baselines and different column
decisions, because many independent trainings are averaged and they do not all land the same way.
Treat a single run as evidence, not as proof. If a column's status matters to a decision you are
making, run it twice.
## What it costs you in time
A run is dominated by the number of columns, not by the number of rows. Each column is a full
round of training, so a 20-column file runs roughly twice as long as a 10-column file on the same
data. Raising the bucket count lengthens it further.
For a sense of scale: a 21-column file at 4 buckets finished in 52 minutes. Wider files, or higher
bucket counts, take longer. The run reports elapsed time and a progress fraction throughout, so
start it and come back.
## Limits
| Limit | Value |
| ---------------------------- | --------------------- |
| Columns in the training file | 70 |
| File size per upload | 510 MB |
| Concurrent runs per user | 5 |
| Signed upload URL lifetime | 60 minutes |
| Target type | Binary classification |
Refinement takes binary targets today; multi-class refinement is a capability we plan to add. Take
a multi-class dataset straight to [Model Crucible](/products/model-crucible), which handles it.
## Cancelling
Cancellation is cooperative. The run finishes the round it is in and then stops, which can take
15 to 20 minutes. The run keeps reporting a running state until it actually stops, so poll until
the state is terminal rather than assuming the cancel took effect.
## What happens next
The natural next step is to hand the finished run straight to
[Model Crucible](/products/model-crucible). The refined train and test files come across as they
are, already split, already reduced, and the target the refinement reached is carried with them.
Nothing is re-uploaded.
You can also just download the refined files and use them elsewhere. The column decisions are
yours either way.
A full run on a public credit-risk dataset, with the numbers.
Create, upload, start, poll, download.