

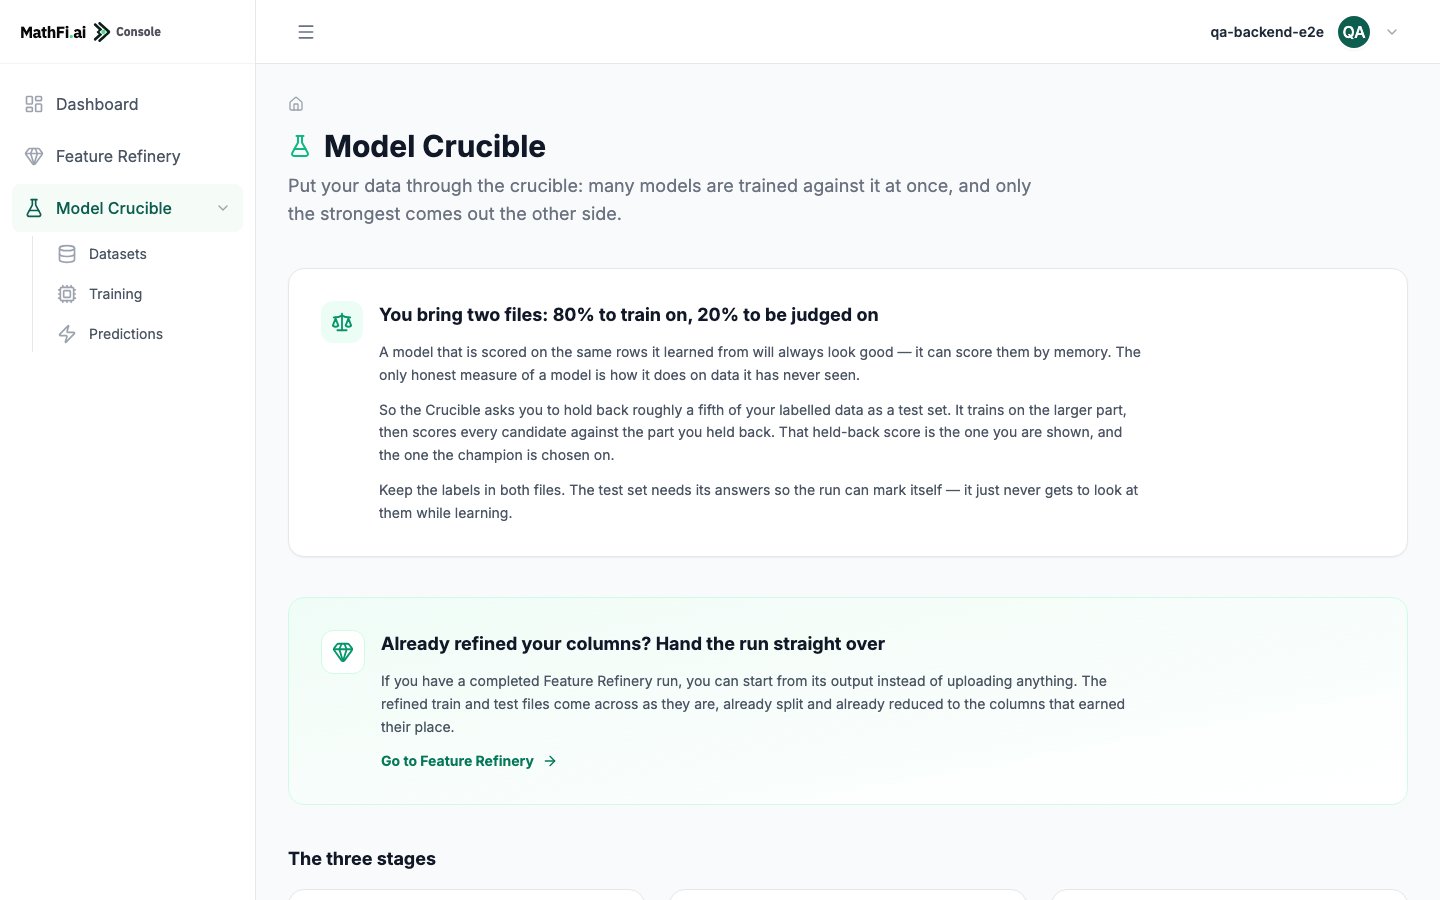
The three stages
1
Dataset
The labelled data to train from. Either a finished Feature Refinery run handed straight over,
or your own 80/20 split uploaded as two files.
2
Training
Every attempt runs at once, and the grid shows each one live. When the run settles, you compare
the three kept models and select one.
3
Prediction
Upload unlabelled rows. They run against the model you selected and come back as a CSV.
Why two files
A model tested on the rows it learned from will always look good. It can answer them from memory. The only honest measure is how it does on data it has never seen. So the Crucible asks you to hold back roughly a fifth of your labelled data as a test set. It trains on the larger part, then tests every candidate against the part you held back. The results on that held-back data are what you are shown, and what you compare when you select a model. Keep the labels in both files. The test set needs its answers so the run can mark itself. It just never gets to look at them while learning. If your data came from Feature Refinery, this is already done. Choose Use Outputs of Refinery and there is nothing to upload.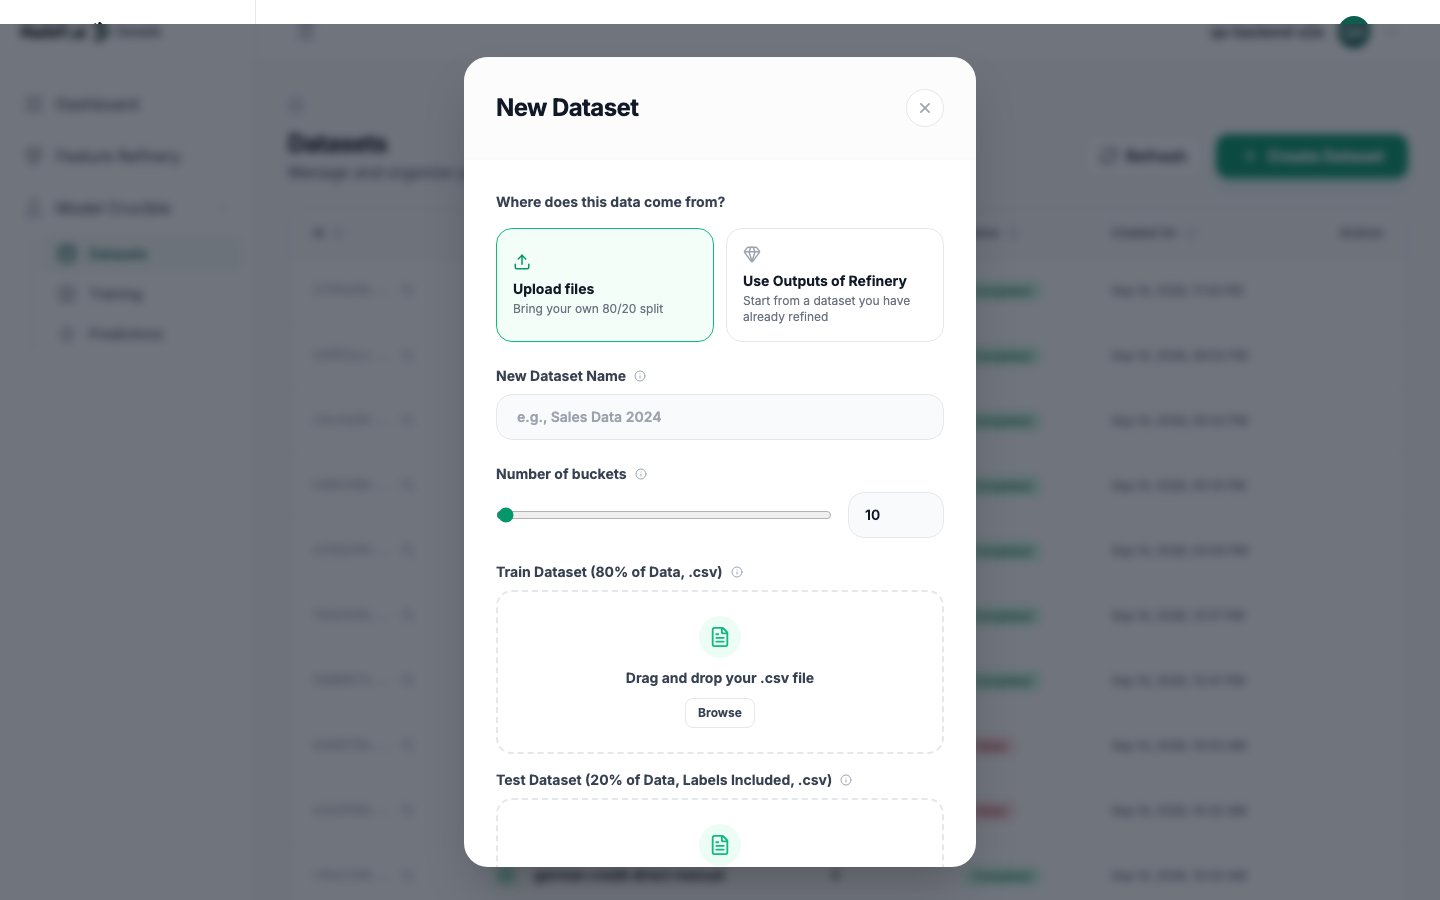
What a training run does
One run is many attempts, not one. It uses three algorithms. One of them varies most from run to run, so it gets 40 attempts. The other two get one attempt each. (Above 50,000 training rows, the many-attempt algorithm gets 20.) All attempts train on the same data and are tested on the same held-back rows. Running many independent attempts is not redundancy, it is the point. Each one attacks the problem from a different starting position. When the pattern in your data shifts, the attempt that was leading may fall behind and another takes over. That diversity is what makes the result hold up as your data moves.How the best three are kept
When the run settles, Crucible keeps the three attempts with the fewest wrong decisions: how many rows the model got wrong on the held-back test set. If attempts tie, F1, then precision, then recall, separate them. Attempts with identical results count as one, so you never see the same model twice. The three are saved as v1, v2 and v3, with the fewest wrong decisions first. Wrong decisions, F1, precision and recall are all shown for each one, so you can compare them.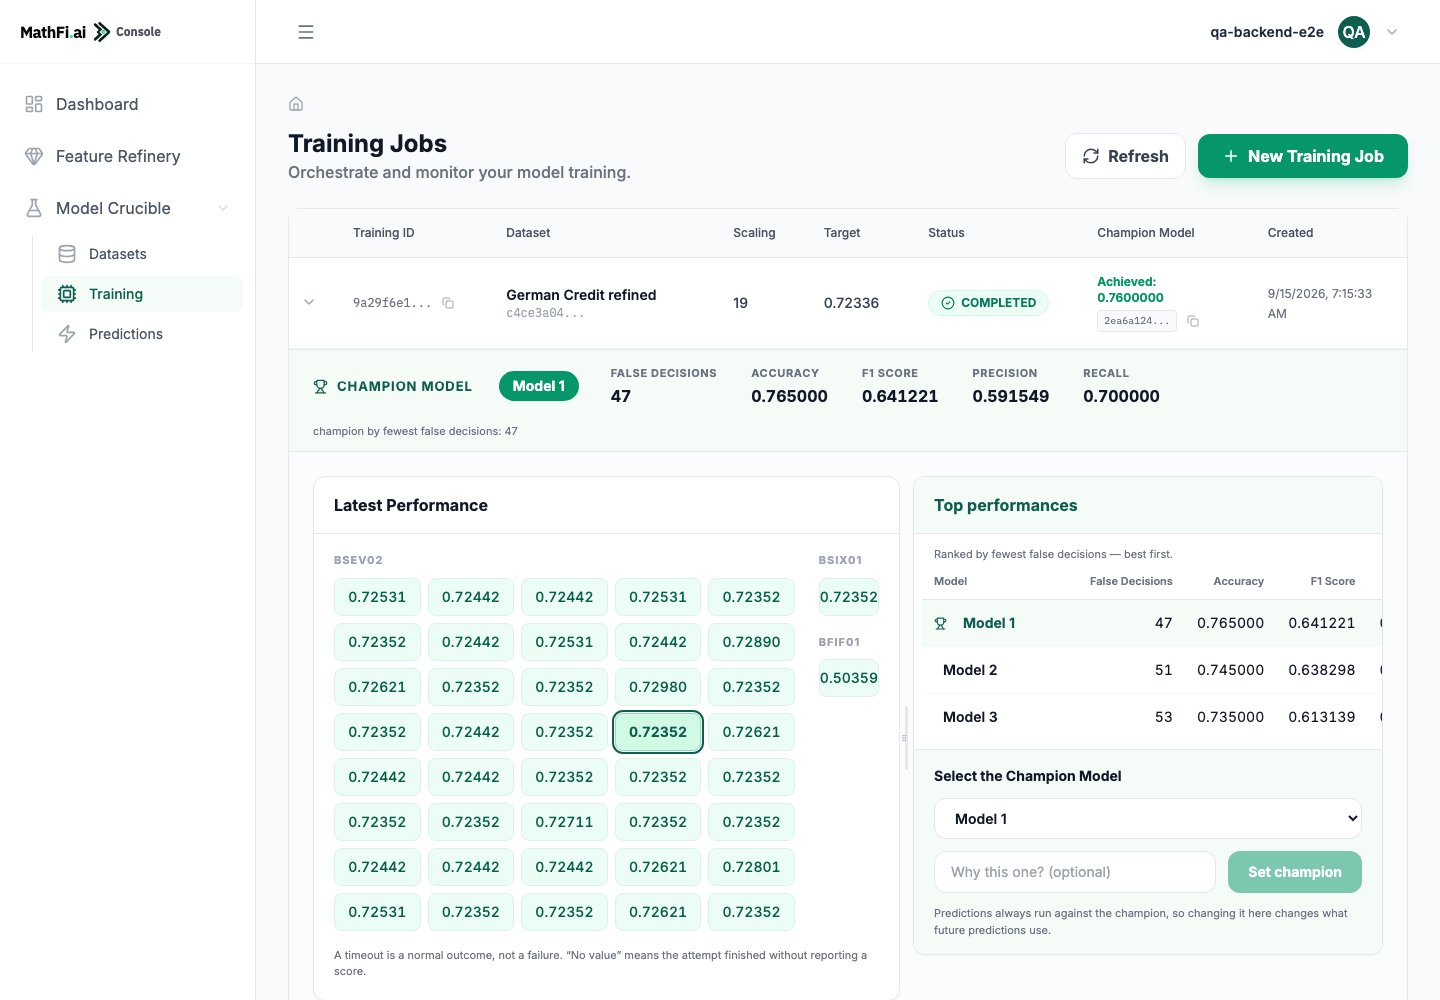
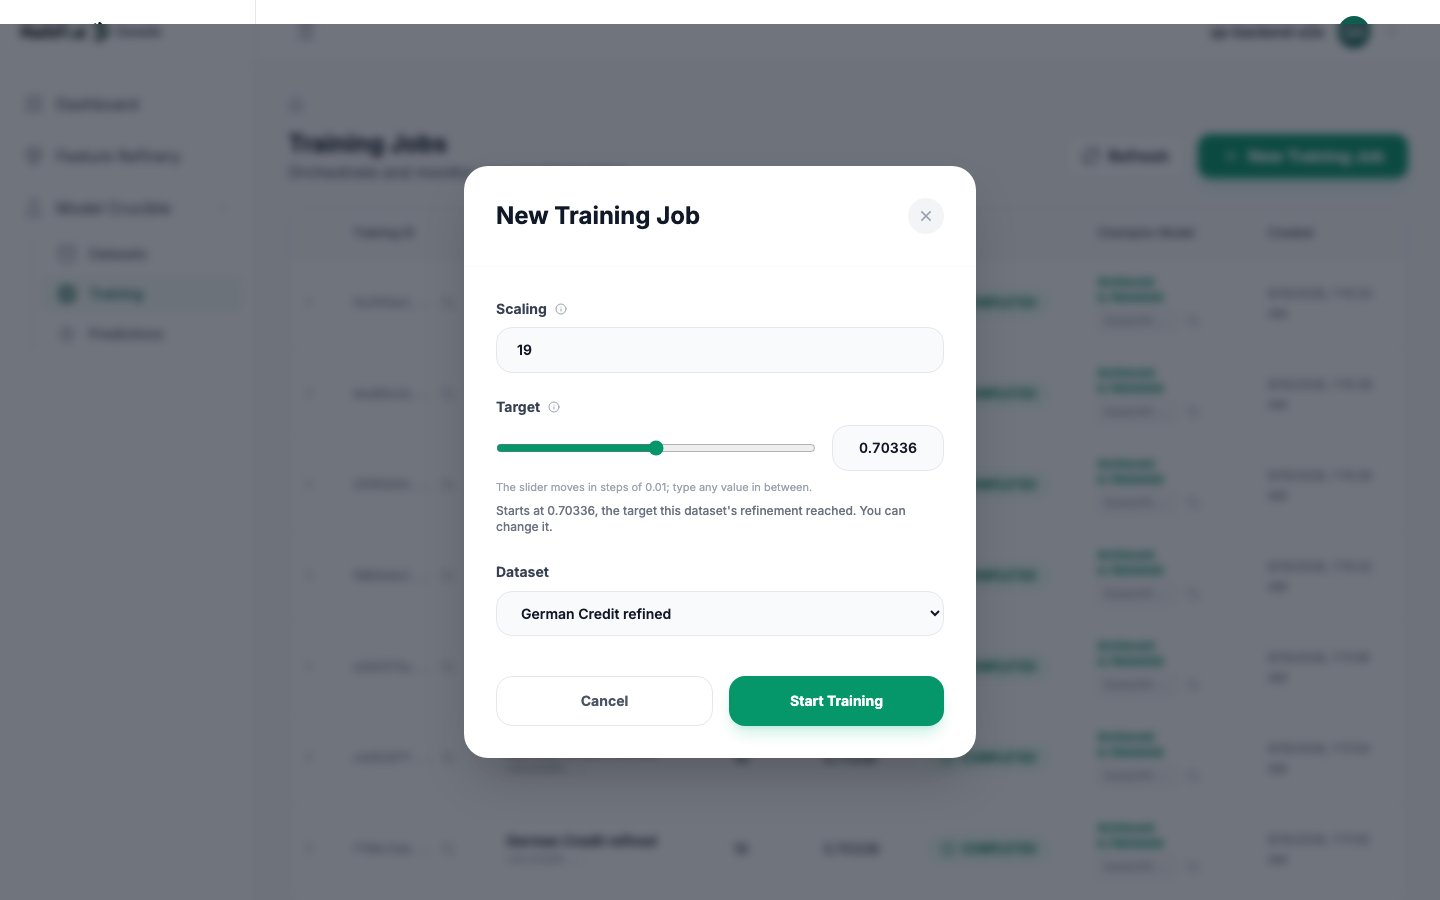
Settings
Selecting a model
A finished run keeps up to three models as v1, v2 and v3. You select the one to predict with. Until you do, predictions use v1, so a finished run is always ready to use.- Predictions run against the model you selected. Selecting another model changes what future predictions use.
- Changing it never rewrites history. Every prediction records the version it ran against, so an earlier result keeps meaning what it meant.
- Nothing is rebuilt when you switch. A flag moves. Switch as often as you like.
Prediction
Upload a CSV with the same columns as your training data, minus the target. You get back the same rows with the prediction appended.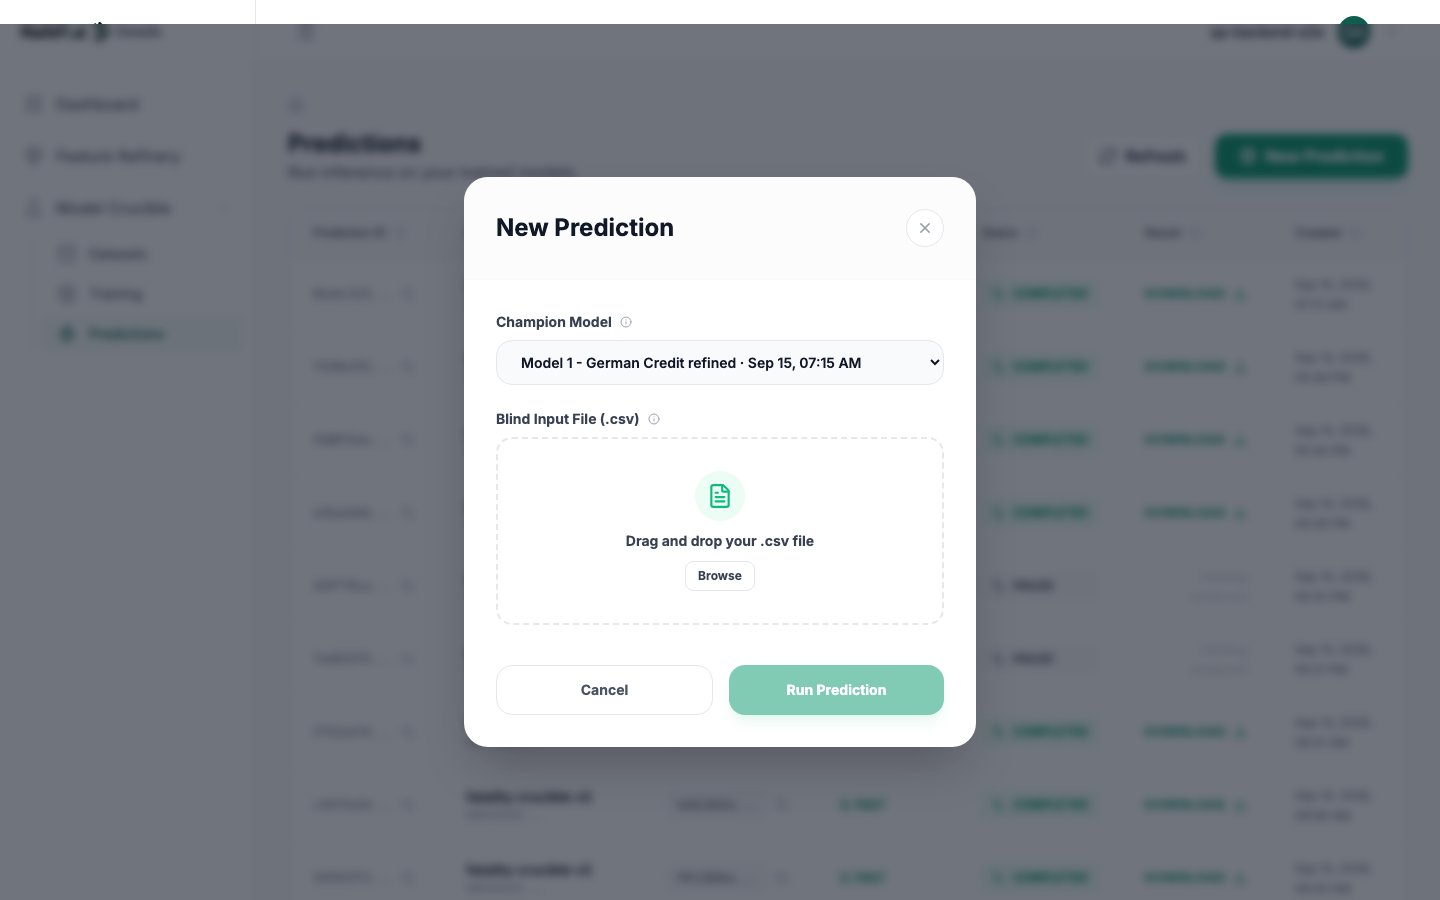
applyColumnStatusFilter option strips them for you, by position. A file you
have already stripped yourself passes through untouched.
Prediction runs on a file: you send a CSV, you get a CSV.
As a benchmark for a model you already have
The Crucible works fine on its own. Upload the same 80/20 split your current model was built on and train. What comes back is an independent model on your data, under your split, compared by wrong decisions, F1, precision and recall. That is a direct answer to a question most teams can only estimate: is the model we already run as good as we think, and on which metric does it fall short? Because it needs no feature engineering from you and no tuning cycle, the comparison costs an afternoon rather than a sprint. Put your current model’s numbers next to the candidates table. The comparison shows you where your model is as good, and where there is a gap. Use the Crucible alone when your feature set is already settled, when your target is multi-class, or when the benchmark is the whole point. The reason to refine first is that most real datasets carry columns that add nothing and a few that actively mislead. Refining removes them and hands over a target that reflects what the cleaned data can actually do. Without it, you are choosing the target yourself, and that choice matters more than anything else you set.Limits
Walk through it
Refinery to Crucible to prediction, with the numbers.
Do it over the API
Dataset, train, poll, choose, predict.